

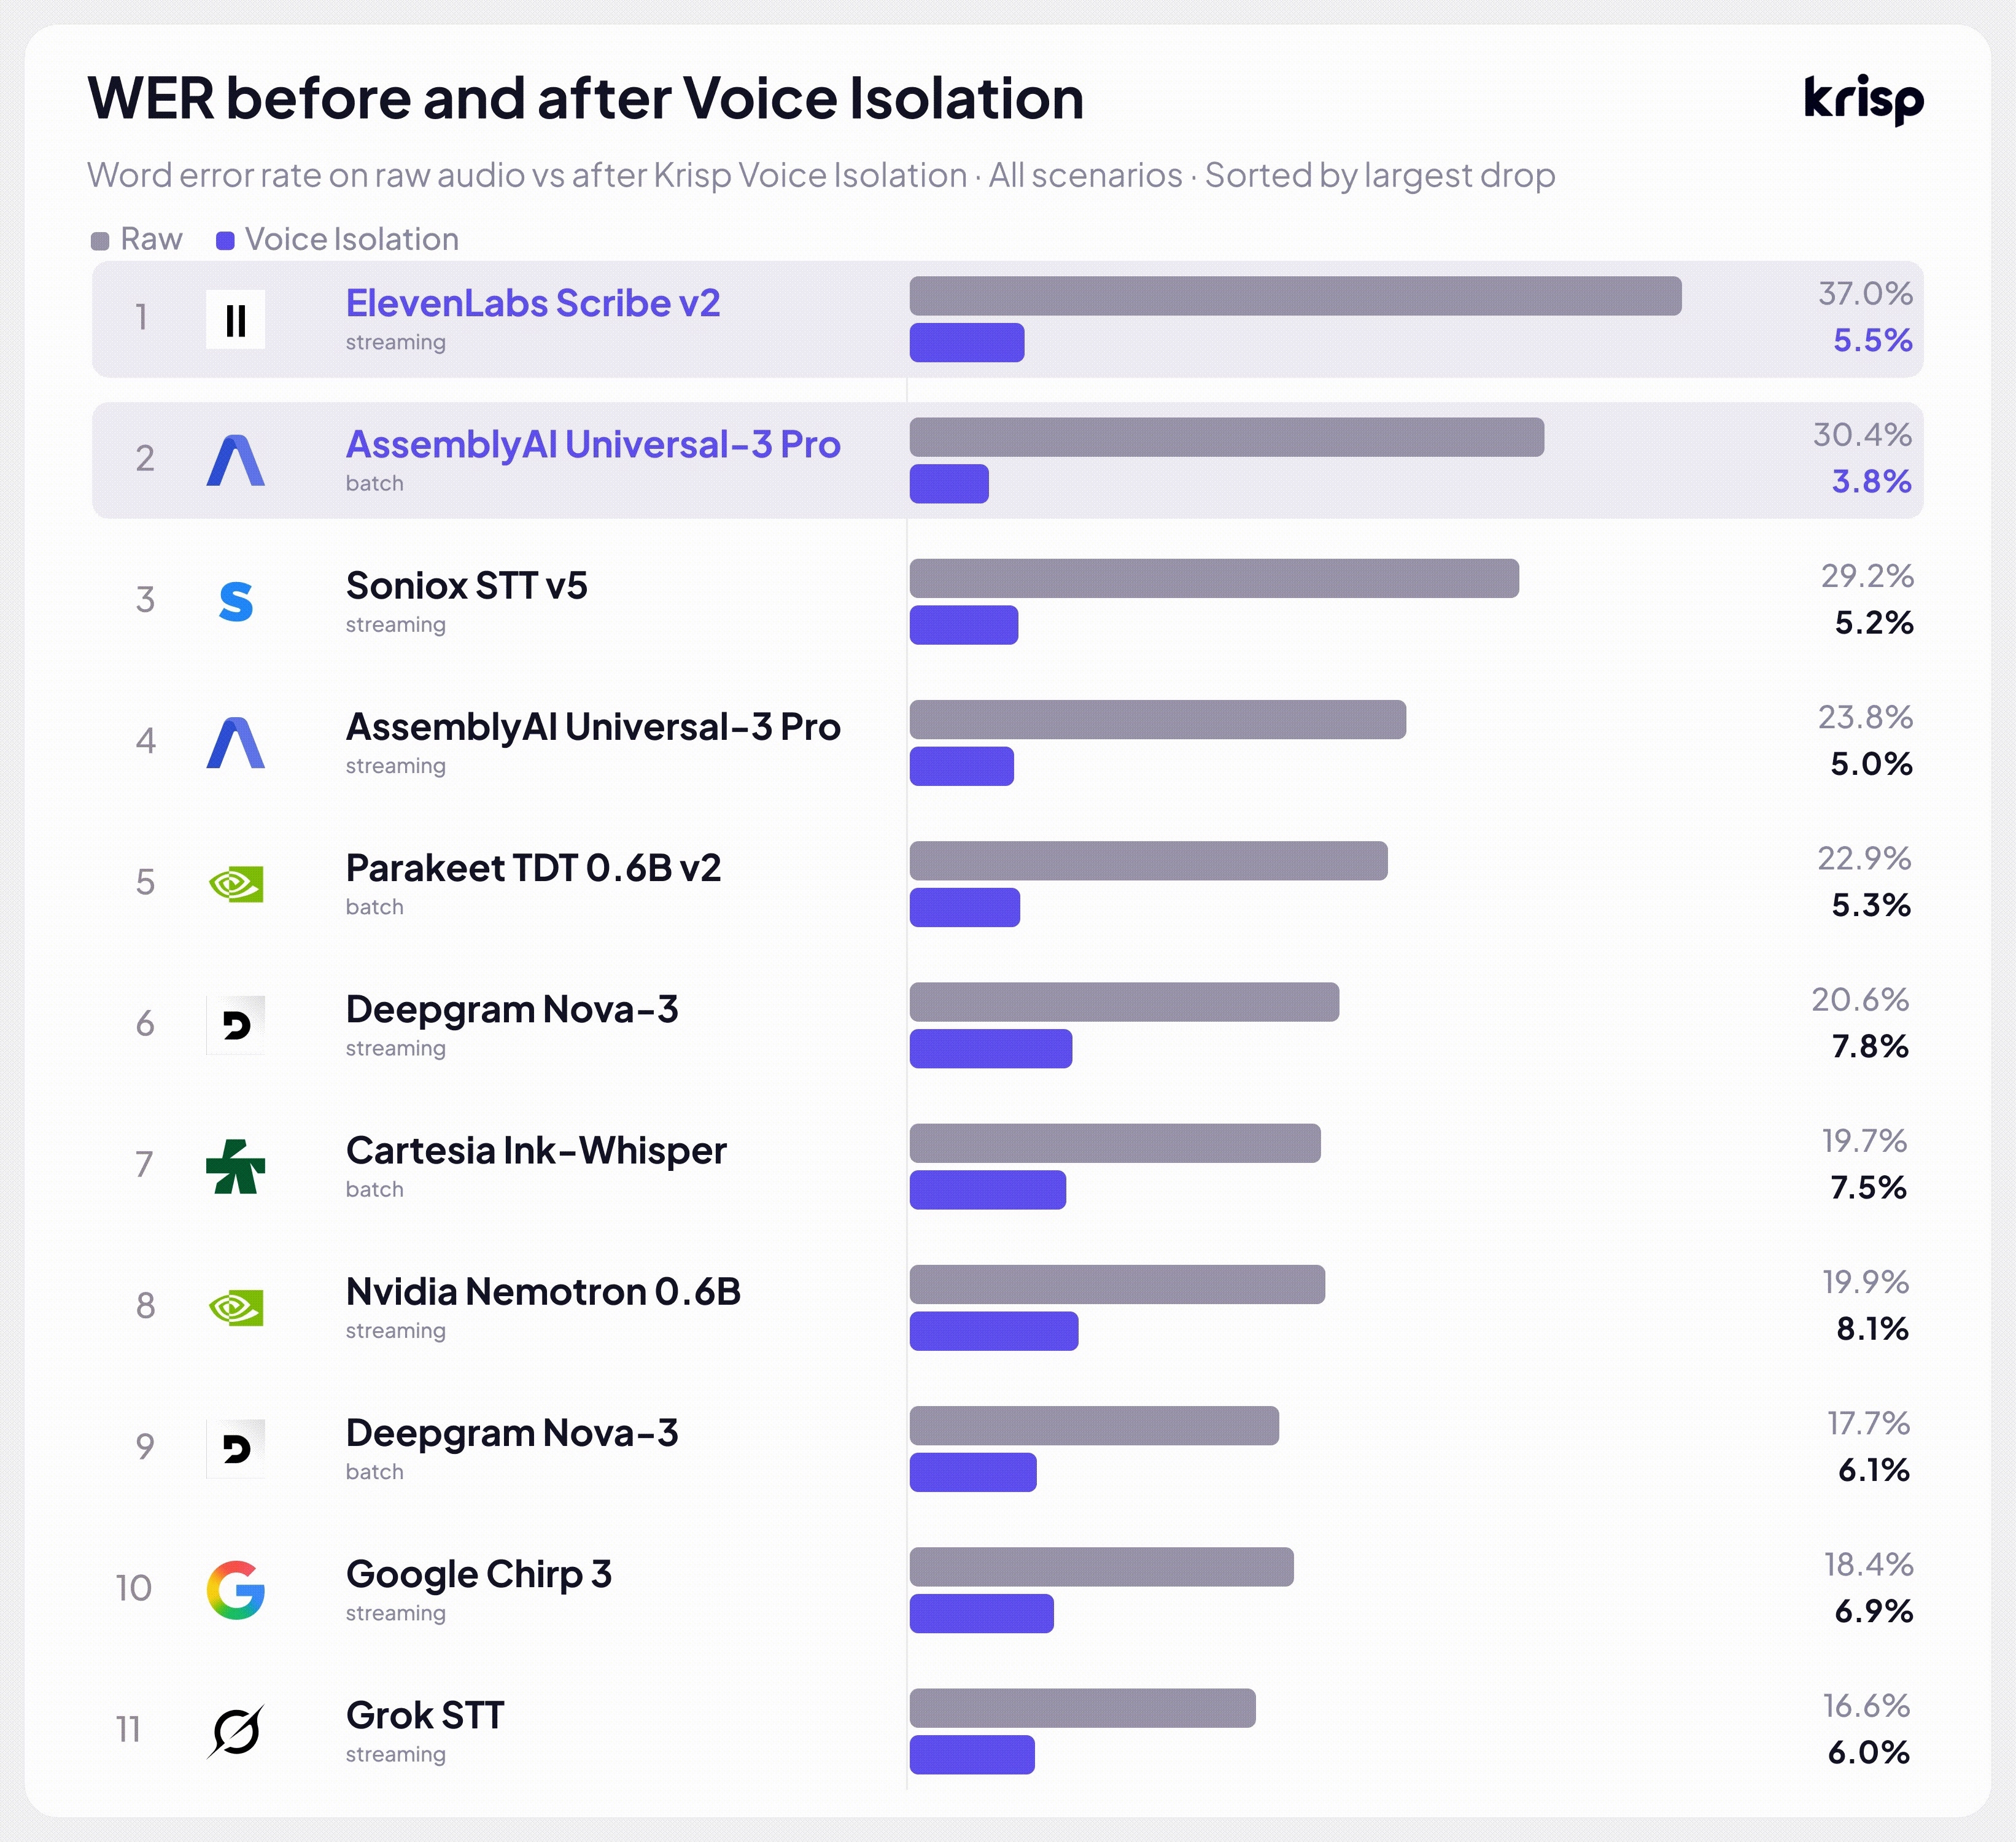
Krisp publishes an open Voice Isolation benchmark, testing 11 STT configurations on real audio with a second voice, where word error rate drops 73%.
Events 🎤
Vonage and Deepgram open Deepgram’s SF HQ for “Voice AI in the Wild” (Oct 6, San Francisco, Partiful)
Agora runs “From Prototype to Production: Scaling Voice AI” (Oct 6, San Francisco, Partiful)
AssemblyAI hosts a hardware hackathon (Oct 7, San Francisco, Luma)
Aqua Voice, Speechmatics, and LiveKit tackle “Solving voice as an interface” (Oct 7, San Francisco, Partiful)
Coval and Cartesia host “Voices in the Room” (Oct 8, San Francisco, Partiful)
Agora brings EdTech leaders together on voice-first learning (Oct 8, London, Luma)
Top Updates 💪
ElevenLabs launches Eleven v4 and v4 Turbo, adding automatic expression control, 10-second voice cloning, and 90+ languages (TechCrunch)
Microsoft ships MAI-Transcribe-2-Streaming plus MAI-Voice 2.1 models, topping the streaming AA-WER benchmark at 2.5% (Unite.AI)
Alibaba releases Qwen-Audio 3.1 Realtime, a full-duplex voice model with 262K context and tool calling, cutting voice API prices up to ~85%. (MarkTechPost)
Inworld acquires Ultravox (formerly Fixie) to add a real-time voice-agent platform with turn-taking and interruption handling to its speech stack. (Morningstar)
Wemnal integrates Krisp VIVA to improve its voice AI agents (LinkedIn)
Modulate raises $25M for voice models and an analysis suite spanning transcription, emotion, deepfake and AI-music detection, and agent policy enforcement. (TechCrunch)
Instinct raises $1B at a $10B valuation for a personal AI agent that calls and texts on users’ behalf, quadrupling its valuation in a month. (SiliconAngle)
Relay raises $36M to turn the frontline push-to-talk radio into an AI assistant that logs and acts on what workers say. (PYMNTS)
Presto raises $10M to expand its drive-thru voice AI across enterprise QSRs, now live in hundreds of locations. (Yahoo Finance)
Deepslate raises $8.8M to build a Europe-hosted speech-to-speech model it bills as the fastest on Artificial Analysis at 440ms. (Tech Funding News)
Klang raises €1.32M and open-sources Pianissimo, a Swedish speech-to-text model that runs locally and builds on NVIDIA Parakeet. (EU-Startups)
ElevenLabs doubles its valuation to $22B, letting employees cash out via a $300M tender offer six months after its $11B raise. (TechCrunch)
AI could bring 10x more Voice work to India (BusinessWorld)
Fireflies launches Fireflies Talk, free unlimited voice dictation across apps on Mac and Windows in 100+ languages. (GlobeNewswire)
Tavus previews Griffin, a full-duplex video-to-video model that sees, hears, and talks back, with 48% of testers thinking it was human. (The Rundown AI)
Suno launches Speech beta, generating synthetic voices with matched background music in one track from a prompt or script. (The Verge)
Mobvoi announces the TicNote Watch, a $249 smartwatch that records, transcribes, and summarizes conversations from the wrist offline. (PR Newswire)
EssilorLuxottica launches Nuance Audio Plus, second-gen open-ear hearing glasses adding iPhone calls and longer battery, from $829. (Wareable)
Starkey unveils Omega AI+, its most advanced hearing aid, built on a new Gen AI neuro processor and quad-DNN architecture. (Fortune)
Logitech launches the Zone Vibe Pro, a boomless headset with AI call noise reduction filtering up to 93% of background sound. (CravingTech)
RingCentral partners with NovelVox to wire contact centers into core banking platforms like Fiserv, FIS, and Jack Henry. (RingCentral)
An AI voice test could screen for Type 2 diabetes, flagging risk from 20 seconds of speech in a 21,000-person study. (Forbes)
Deepfake defense draws new capital, with voice-detection checks forecast to near $5.5B by 2028 as fraud screening scales. (Biometric Update)
Telecom Reseller argues contact centers should own their voice layer, with Gladia’s CEO framing voice AI as core infrastructure, not an add-on. (Telecom Reseller)
Engineering Corner 😎
FermionResearch releases Phonon-2, the most accurate open English ASR model under 900MB at 5.21% WER, in a 164MB download. (Hugging Face)
A comparison of OpenAI, Gemini, and Qwen realtime voice APIs finds up to a 213x gap in per-minute cost across the three. (Tech Insider)
whisper-local ships offline push-to-talk dictation, a free faster-whisper tool that types at the cursor in any app, fully on-device. (PyPI)
A paper proposes inference-time target-speaker unlearning in ASR, letting a speaker opt out of meeting transcription without leaving the call. (arXiv)
Linux Journal shows adding speech synthesis to scripts and systems, using TTS APIs to voice Linux services without hosting a model. (Linux Journal)
A breakdown of voice-agent latency explains why response delay kills calls and how to cut it through the STT, LLM, and TTS stack. (AI in Plain English)
A dev essay on why AI voices wear thin after three minutes dissects the “30-second trap” of long-form synthetic narration. (dev.to)
Perficient briefs on NotebookLM and Wispr Flow, pairing source-grounded research with voice dictation for content workflows. (Perficient)